

MemantoClaw
MemantoClaw is an open-source reference stack that simplifies running OpenClaw always-on assistants safely with built-in long-term memory. It combines three core technologies:- Autonomy (OpenClaw): A powerful open-source agent framework.
- Security (NVIDIA OpenShell): A hardened sandbox that restricts network egress and file access.
- Memory (Memanto): A long-term memory architecture powered by Moorcheh that carries context across sessions.
🏗️ Architecture
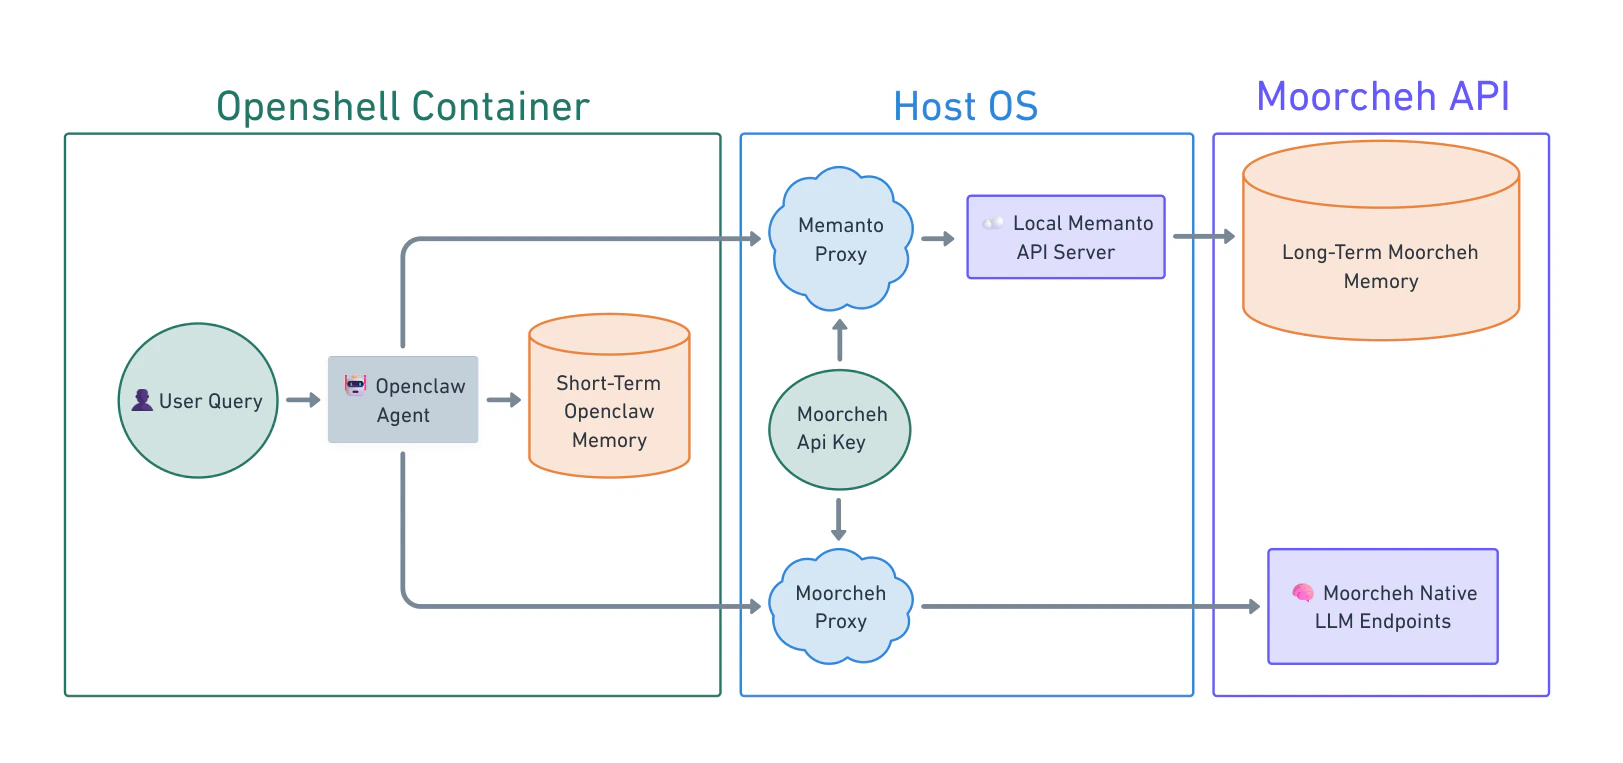
- The host manages credentials and provider routing to long-term memory services.
- The sandbox runs OpenClaw under OpenShell policy enforcement.
- The agent receives only the context it needs for each task, not raw host credentials or memory databases.
The Ecosystem and How the Stack Fits Together
Three pieces usually appear together in a MemantoClaw deployment, each with a distinct scope:
MemantoClaw sits above OpenShell in the operator workflow. It drives OpenShell APIs and CLI to create and configure the sandbox that runs OpenClaw. Models and endpoints sit behind OpenShell’s inference routing. MemantoClaw onboarding wires provider choice into that routing, and inherently injects the Memanto memory bridge.
MemantoClaw Path versus OpenShell Path
Both paths assume OpenShell can sandbox a workload. The difference is who owns the integration work.- MemantoClaw path: You adopt the reference stack. MemantoClaw’s blueprint encodes a hardened image, default policies, Moorcheh integration, and orchestration so
memantoclaw onboardcan provision a validated environment with minimal manual configuration. - OpenShell path: You use OpenShell as the platform and supply your own container, install steps, policy YAML, provider setup, and any host bridges.
What MemantoClaw Adds Beyond the OpenShell Community Sandbox
The Memanto Advantage
Unified API Key for Memory and Inference
MemantoClaw simplifies credential management by bundling both long-term memory access and native LLM inference into a single API key. Instead of juggling separate keys for your vector database (or Moorcheh memory service) and your LLM inference provider, your Moorcheh API key authenticates both. When you runmemantoclaw onboard, you provide this one key, and MemantoClaw automatically configures the OpenShell inference gateway to proxy your LLM requests while simultaneously enabling the zero-config memory bridge.
Secure and Real-time Memory
By leveraging Moorcheh’s infrastructure, the Memanto memory layer offers zero-wait ingestion (no indexing delays) and a secure host-bridge architecture where memory stays safely on Moorcheh, and the sandbox only receives specific retrieved context.Deep Dive: How It Works
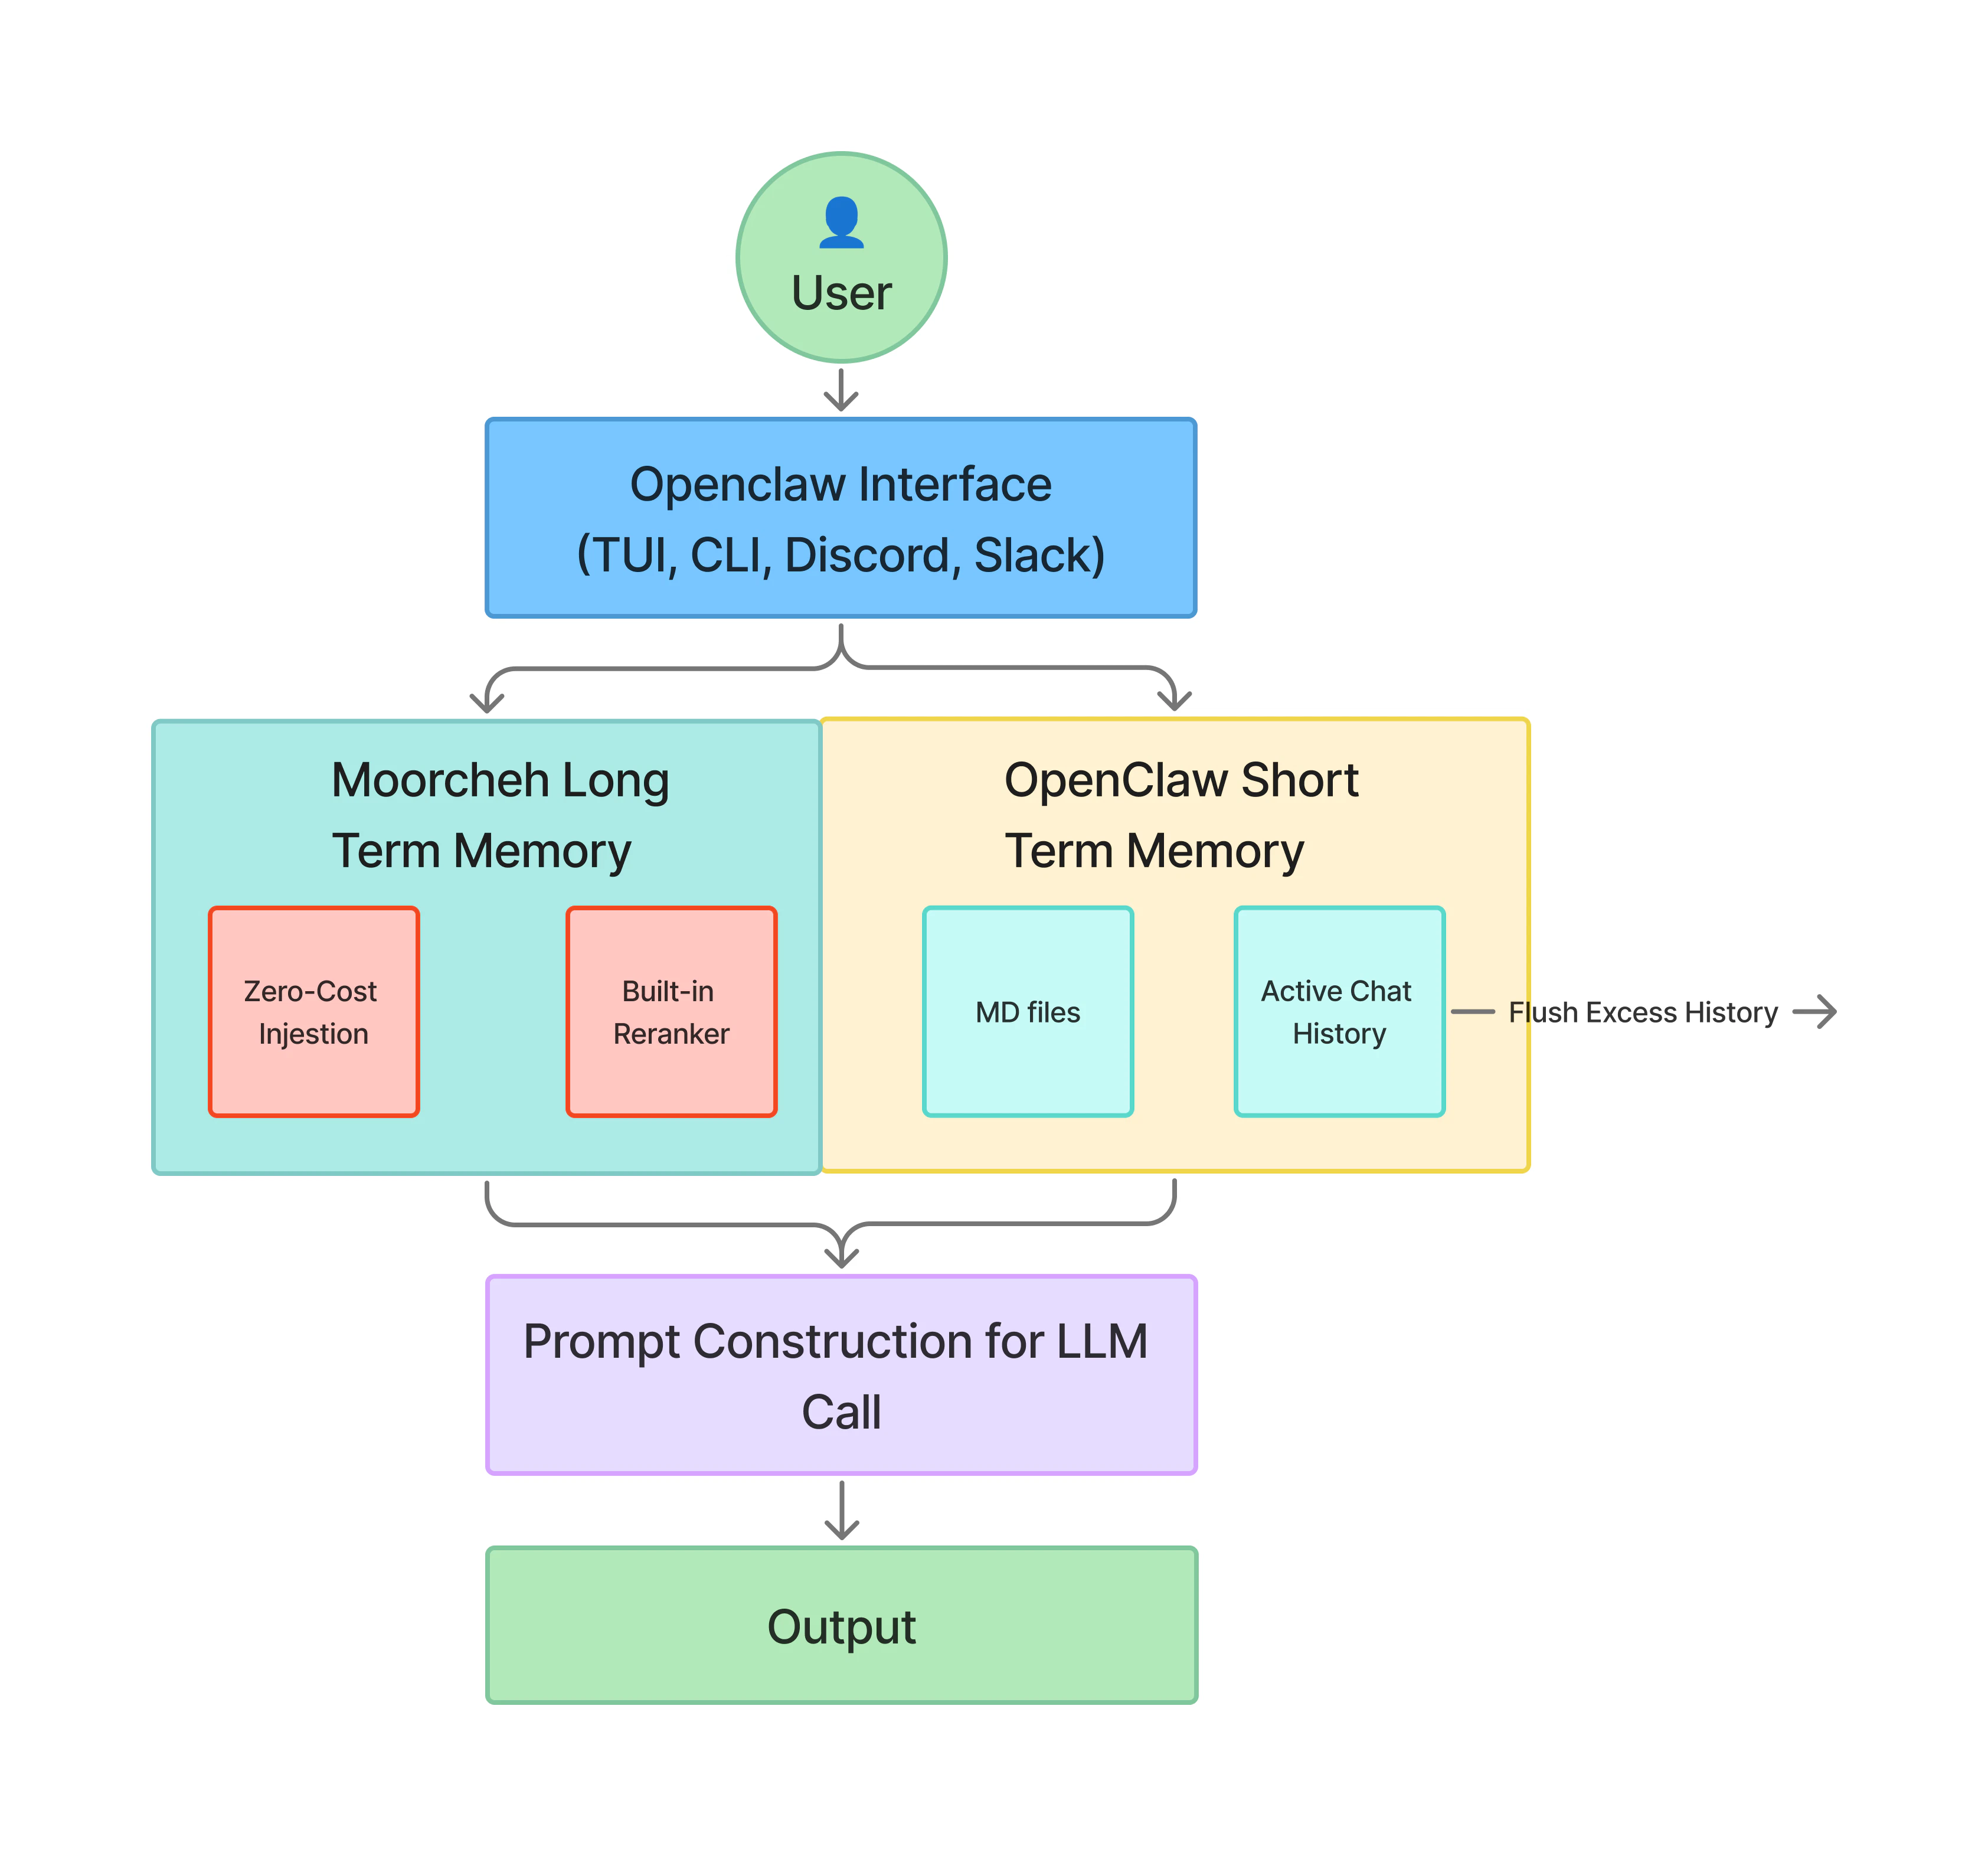
For complete, unabridged technical details on this topic, refer to the official NVIDIA NemoClaw Documentation. Portions of this guide are summarized and adapted from NVIDIA Corporation (Copyright © 2026), licensed under the Apache License, Version 2.0.
Quickstart & Windows Setup
MemantoClaw provides a CLI to launch and manage a sandboxed OpenClaw instance easily.Prerequisites
- A valid
MOORCHEH_API_KEY. - Docker installed and running on your system.
Windows Prerequisites
Running MemantoClaw on Windows requires WSL 2 (Windows Subsystem for Linux).- Enable WSL 2: Open an elevated PowerShell and run
wsl --install --no-distribution. Reboot if prompted. - Install Ubuntu: Open an elevated PowerShell and run
wsl --install -d Ubuntu. Let it finish first-run setup. - Install Docker Desktop: Install Docker Desktop with the WSL 2 backend. Confirm WSL integration is enabled for your Ubuntu distribution.
- Local Ollama (Optional): If using Ollama, install it inside WSL:
curl -fsSL https://ollama.com/install.sh | sh.
Installation
Install the CLI using the installer script (run this in your WSL/Linux terminal):Launching the Sandbox
Start the interactive onboarding wizard to configure your sandbox. The wizard will prompt you to select your inference provider and securely enter yourMOORCHEH_API_KEY.
Note: For MemantoClaw-managed environments, always usememantoclaw onboardwhen you need to create or recreate the OpenShell gateway or sandbox. Avoid using rawopenshellcommands for these lifecycle events.
Deploy to a Remote GPU Instance
You can deploy MemantoClaw to a remote GPU instance (e.g., Brev, AWS). The preferred path is to provision the VM, run the standard installer on that host, and then runmemantoclaw onboard.
For complete, unabridged technical details on this topic, refer to the official NVIDIA NemoClaw Documentation. Portions of this guide are summarized and adapted from NVIDIA Corporation (Copyright © 2026), licensed under the Apache License, Version 2.0.
Inference Options
MemantoClaw supports multiple inference providers. During onboarding, thememantoclaw onboard wizard presents a list of providers to choose from. Your selection determines where the agent’s inference traffic is routed.
How Inference Routing Works
The agent inside the sandbox talks toinference.local. It never connects to a provider directly. OpenShell intercepts inference traffic on the host and forwards it to the provider you selected. Provider credentials stay entirely on the host.
Provider Options
Switching Inference Models at Runtime
You can change the active inference model while the sandbox is running. No restart is required. Switching happens through the OpenShell inference route.Cross-Provider Switching
Switching to a different provider family requires updating both the gateway route and the sandbox config.Using a Local Inference Server
MemantoClaw can route inference to a model server running on your machine.Ollama
Ollama is the default local option. The wizard detects it automatically. On Linux with Docker, the sandbox reaches Ollama throughhttp://host.openshell.internal:11434. Make sure Ollama listens on 0.0.0.0:11434.
OpenAI/Anthropic Compatible Servers
Works with vLLM, TensorRT-LLM, llama.cpp, LocalAI, etc. Select “Other OpenAI-compatible endpoint” and enter your base URL (e.g.,http://localhost:8000/v1). The wizard will probe /v1/responses and fall back to /v1/chat/completions if streaming events are incompatible.
Experimental Local vLLM & NVIDIA NIM
SetMEMANTOCLAW_EXPERIMENTAL=1 to enable vLLM auto-detection on localhost:8000 or NIM container management on hosts with NIM-capable NVIDIA GPUs.
Timeout Configuration
Local inference requests use a default timeout of 180 seconds. Increase it if needed:For complete, unabridged technical details on this topic, refer to the official NVIDIA NemoClaw Documentation. Portions of this guide are summarized and adapted from NVIDIA Corporation (Copyright © 2026), licensed under the Apache License, Version 2.0.
Network Policies
MemantoClaw runs with a deny-by-default network policy. The sandbox can only reach endpoints that are explicitly allowed. Any request to an unlisted destination is intercepted by OpenShell.Baseline Policy
The baseline policy is defined inmemantoclaw-blueprint/policies/openclaw-sandbox.yaml.
- Filesystem:
/sandbox,/tmp,/dev/nullare Read-write./usr,/lib,/proc,/app,/etcare Read-only. - Network: Endpoints like
openclaw.ai:443,docs.openclaw.ai:443,registry.npmjs.org:443are allowed. - Inference: The baseline policy allows only the
localinference route.
Operator Approval Flow
When the agent attempts to reach an unlisted endpoint, OpenShell intercepts the request interactively.- Open the TUI:
openshell term - Trigger a blocked request (the agent tries to reach an unknown host).
- The TUI displays the Host, Port, Binary, and HTTP method of the request.
- Approve to add the endpoint for the current session, or Deny to keep it blocked.
Customize the Sandbox Network Policy
Static Changes
Editmemantoclaw-blueprint/policies/openclaw-sandbox.yaml. Each entry defines endpoints, binaries, and rules (methods). Then re-run:
Dynamic Changes
Create a YAML policy file and apply it to a running sandbox instantly:Policy Presets
MemantoClaw ships preset policy files for common integrations (e.g.,github, npm, pypi, discord, slack). To apply a preset to a running sandbox:
For complete, unabridged technical details on this topic, refer to the official NVIDIA NemoClaw Documentation. Portions of this guide are summarized and adapted from NVIDIA Corporation (Copyright © 2026), licensed under the Apache License, Version 2.0.
Workspace Files
Workspace files define your agent’s personality, memory, and user context. They persist across sandbox restarts but are permanently deleted when you runmemantoclaw <name> destroy.
These files live at /sandbox/.openclaw/workspace/ inside the sandbox.
File Reference
The Memanto Advantage
In standard open-source setups, OpenClaw relies on a local SQLite database for recent chat history (using BM25 keyword matching) and manual markdown files likeMEMORY.md for facts. This approach is lossy, degrades over time, and if the sandbox is destroyed, the agent suffers total amnesia of its conversational context.
With MemantoClaw, long-term semantic memory is securely routed to Moorcheh’s information-theoretic search engine via the host bridge. Even if you destroy the sandbox, the retrieved context and learned knowledge safely persist remotely, ready to be injected into your next agent immediately.
Back Up and Restore Workspace Files
Use the OpenShell CLI to manually copy local Markdown files out of the sandbox before destroying it:Using the Backup Script
MemantoClaw includes a convenience script:For complete, unabridged technical details on this topic, refer to the official NVIDIA NemoClaw Documentation. Portions of this guide are summarized and adapted from NVIDIA Corporation (Copyright © 2026), licensed under the Apache License, Version 2.0.
Security Best Practices
MemantoClaw enforces security at four layers: Network, Filesystem, Process, and Inference.Layer Protections
- Network Layer: Deny-by-default egress. Configured via OpenShell policy. Binary-Scoped rules ensure only authorized binaries (like
ghorgit) can access specific endpoints. - Filesystem Layer: Uses Landlock LSM + container mounts.
/sandboxis read-only, while specific paths like/sandbox/.openclaw-dataand/tmpare writable. Gateway config (/sandbox/.openclaw) is immutable and hash-pinned. - Process Layer: Drops dangerous Linux capabilities using
capsh. Setsulimit -u 512to mitigate fork-bomb attacks. Enforcesno-new-privilegesto block privilege escalation via setuid binaries. Removes build toolchains (gcc,make) andnetcatfrom the image. - Inference Layer: Routes model API calls to controlled backends via
inference.local.
Credential Storage
Credentials (likeMOORCHEH_API_KEY, OPENAI_API_KEY) are stored in plaintext JSON at:
~/.memantoclaw/credentials.json
They are created with mode 0600 on the host. They are never injected into the sandbox. The host bridge authenticates requests before forwarding them. If you suspect exposure, rotate keys and remove the stored file:
OpenClaw Controls
MemantoClaw delegates application-layer security to OpenClaw. OpenClaw provides:- Prompt Injection Detection: Neutralizes attempts like
<system>tag spoofing. - Tool Access Control: High-risk tools (
exec,spawn,fs_write) are gated by a multi-layer policy pipeline. - Environment Variable Security: Blocks dangerous env vars (
NODE_OPTIONS,LD_PRELOAD). - Secret Scanner: Intercepts writes targeting memory paths that look like API keys before they reach the disk.
For complete, unabridged technical details on this topic, refer to the official NVIDIA NemoClaw Documentation. Portions of this guide are summarized and adapted from NVIDIA Corporation (Copyright © 2026), licensed under the Apache License, Version 2.0.
Operations and Troubleshooting
Use the MemantoClaw status, logs, and TUI tools together to inspect sandbox health and trace agent behavior.Monitor Sandbox Activity
Check Health
View Logs
Open TUI
Troubleshooting Common Issues
- Installer fails on Node.js: MemantoClaw requires Node.js 22.16+. Install it using
nvm use 22. - Docker permission denied: Ensure your user is in the
dockergroup (sudo usermod -aG docker $USER). - OOM errors during sandbox creation: Image push requires memory. Add at least 8 GB of swap file on smaller machines.
- Port already in use: The gateway uses port
18789. Terminate conflicting processes (sudo lsof -i :18789). - Sandbox lost after gateway restart: Upgrade OpenShell to >= 0.0.24 via
memantoclaw onboard. - Inference unreachable: Check if Ollama/vLLM is running. Increase timeout (
MEMANTOCLAW_LOCAL_INFERENCE_TIMEOUT=300) for slow hardware.
Agent Skills for AI Coding Assistants
MemantoClaw ships agent skills generated directly from documentation. These allow coding assistants (like Cursor, Claude Code) to read project-specific guidance. Fetch the skills via sparse checkout:For complete, unabridged technical details on this topic, refer to the official NVIDIA NemoClaw Documentation. Portions of this guide are summarized and adapted from NVIDIA Corporation (Copyright © 2026), licensed under the Apache License, Version 2.0.
Commands
Thememantoclaw CLI handles host-side operations outside the OpenClaw plugin context.
Standalone Host Commands
For complete, unabridged technical details on this topic, refer to the official NVIDIA NemoClaw Documentation. Portions of this guide are summarized and adapted from NVIDIA Corporation (Copyright © 2026), licensed under the Apache License, Version 2.0.